How FiberHMM works
The problem
Single-molecule chromatin assays mark accessible DNA: m6A methylation by Hia5, or cytosine deamination by DddA/DddB. Marking efficiency depends strongly on the local sequence: in accessible DNA some contexts are marked most of the time, others rarely. A threshold that ignores this over-calls footprints in poor contexts and misses them in good ones, and small footprints (10–30 bp for a transcription factor) are lost in the noise.
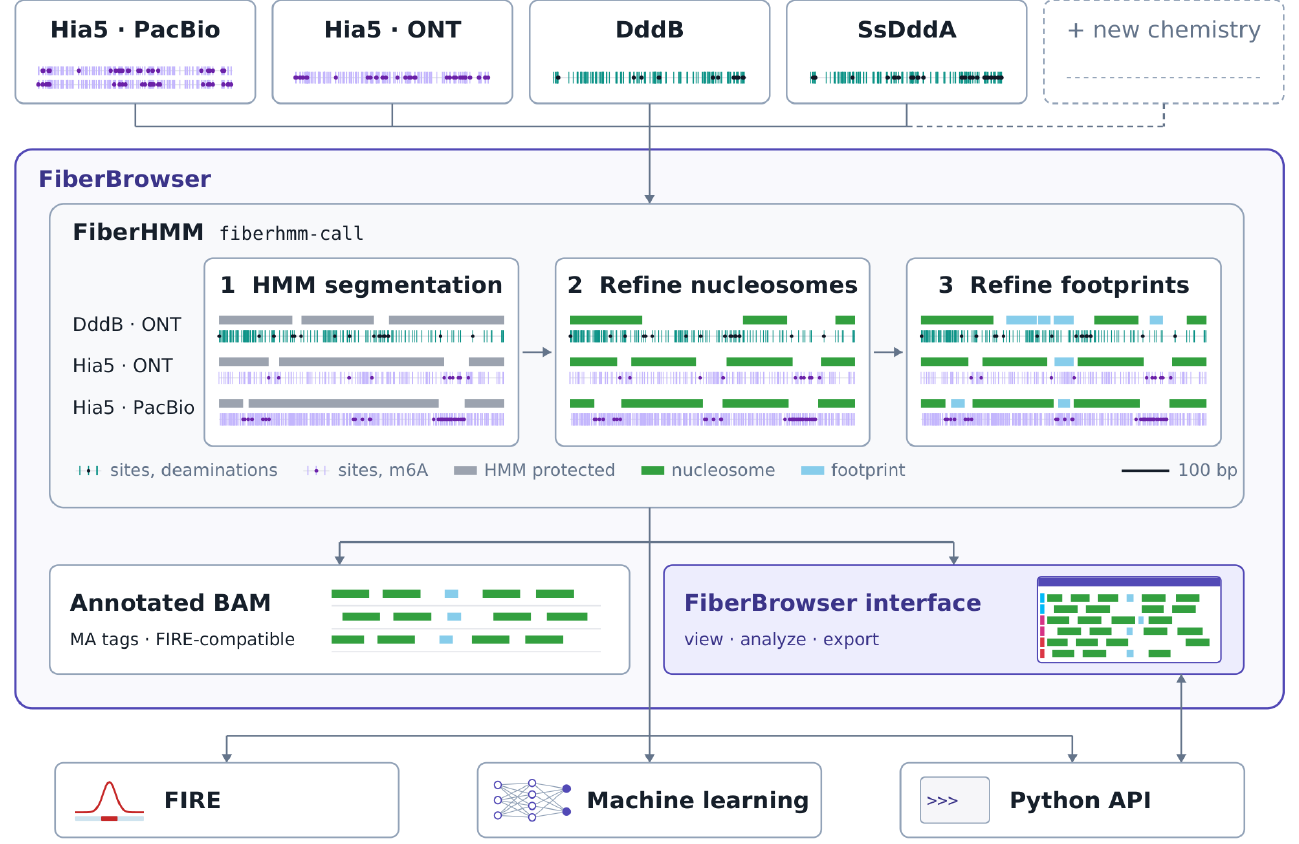
Reads from each chemistry go through fiberhmm-call in three steps: HMM segmentation (gray), nucleosome refinement (green) and footprint refinement (sky blue). The calls are written to the BAM as MA tags for FiberBrowser, FIRE and other tools. From the preprint.
The model
For every target base FiberHMM takes the k bases on each side from the read (a 7-mer for k = 3; no reference is needed) and looks up, in an emission table estimated from accessible and inaccessible controls, the probability of a mark in the protected and in the accessible state.
- HMM. A two-state HMM (protected, accessible) with these
context-specific emissions is decoded with Viterbi. Protected runs are
footprints; the accessible stretches between nucleosome-sized footprints
are MSPs. For DddA, CpG observations are left out (5-methylcytosine slows
deamination, so a methylated CpG looks protected) except inside CpG
islands called unmethylated by
fiberhmm-tag-m5c. - Nucleosome recall. Nucleosome-sized footprints are re-examined for buried linkers (accessible evidence inside the footprint) and split there, and each piece gets conservative edges from its protected evidence. For DddA, which also deaminates inside nucleosomes, a phase-aware radial caller places nucleosomes from the helically phased deamination profile instead.
- TF recall. Inside accessible regions, a log-likelihood-ratio recaller
chooses the set of protected intervals that maximizes the summed
protected-versus-accessible evidence minus a fixed cost per interval
(5 nats), an exact linear-time dynamic program. Each call gets
tq = 10 × LLRand edge-sharpness bytes.
Emission tables come from fiberhmm-probs (control BAMs) and transitions
from fiberhmm-train (Baum-Welch). Tables are indexed by the encoder's
context code (bases numbered A, C, T, G).
Across molecules
fiberhmm-consensus discovers recurrent footprint classes from confident
per-read calls and scores every molecule's own marks against them with EM,
per strand or channel, reporting each class's prevalence, support and
per-molecule membership. fiberhmm-transfer measures frozen classes in new
data.
More detail: How FiberHMM works and Footprint classes.